Microsoft 365 Outage: The July Bug That Broke Outlook
Published (Updated )
Microsoft 365 Outage: The July Bug That Broke Outlook
Quick answer
- Microsoft has explained the global Microsoft 365 outage of Thursday, November 12, 2026 — and the root cause was a software defect that had been sitting in its systems since July.
- The defect caused lock contention inside an internal process, leaving networking gateway servers overwhelmed and unresponsive when load spiked.
- Two other factors made it far worse: Teams had failed over to the same gateway about 15 hours earlier, and nearly 14% of gateway capacity was already out of service.
- At the worst point, more than 80% of the networking gateway servers were unresponsive, and Outlook stayed down longest because Exchange Online could not fail over.
- Microsoft says there was no malicious activity and no cyberattack. Engineers reverted the faulty code, and a full Post-Incident Review was due later in the week.
What happened on November 12
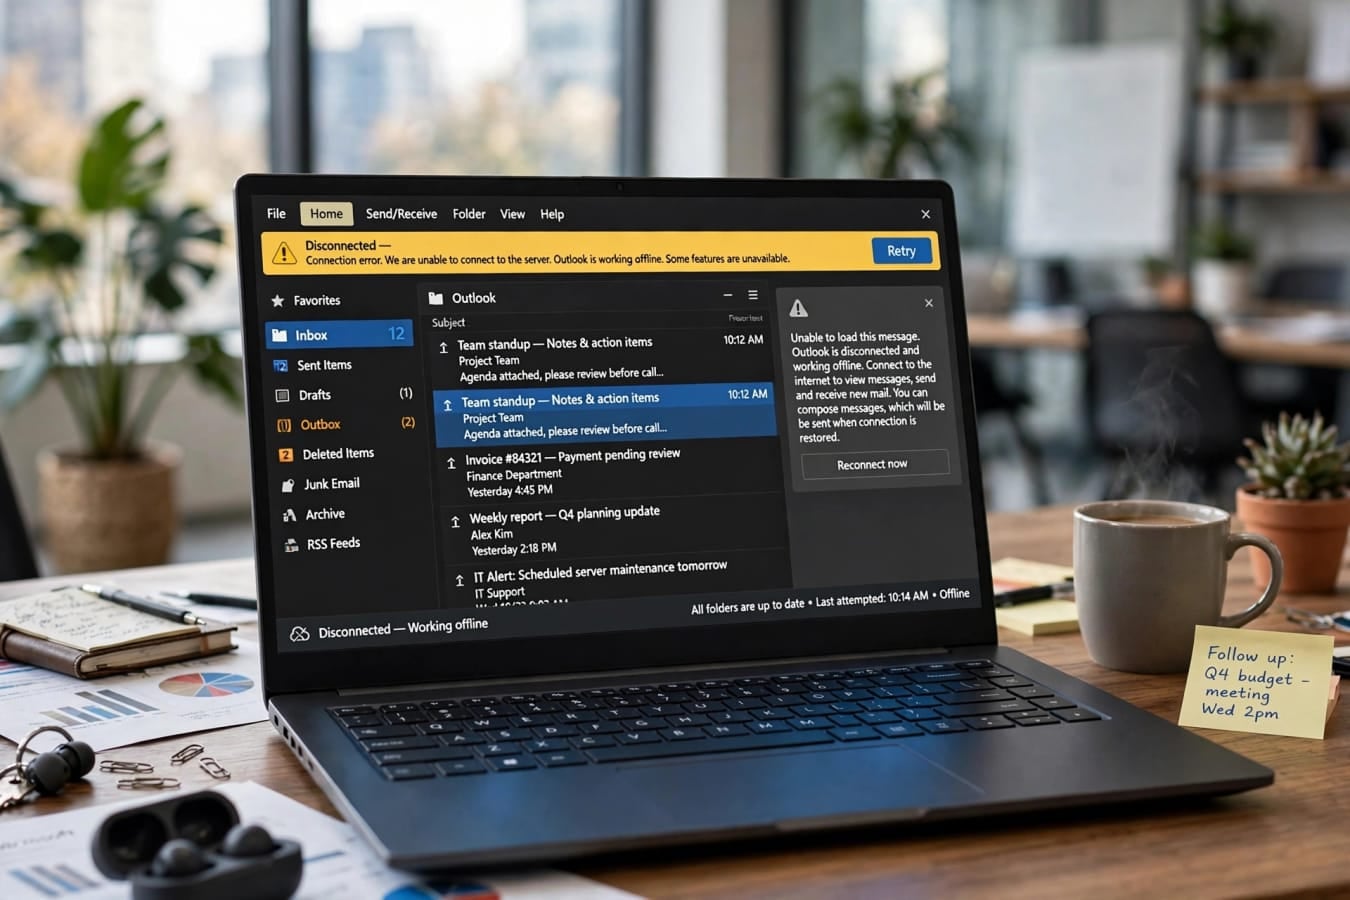
It started as a bad morning for millions of workers. On Thursday, November 12, 2026, Outlook stopped working for users around the world. Emails would not send, inboxes would not load, and calendars were unreachable. Microsoft first flagged the problem at 11:24 pm IST on November 12, but by then the outage was already spreading fast. Within hours it had reached more than 70 countries, and Downdetector recorded between 120,000 and 130,000 reports at the peak. The outage lasted more than 24 hours for many users. Outlook was hit hardest, but it was far from the only service affected:
- Outlook and Exchange Online — email, calendars and contacts unavailable
- Microsoft Teams — meetings, chats and calls disrupted
- OneDrive and SharePoint — files and document libraries unreachable
- Office apps — Word, Excel and PowerPoint online services affected
- Microsoft Copilot — AI assistant features unavailable
- Microsoft Graph — the backbone API behind many 365 services
- Planner, Intune, Purview and Power BI — also caught up in the outage
The impact went well beyond office workers checking email. Government offices, courts and hospitals were among the organisations hit, with staff unable to reach the email and documents they rely on every day.
For a service that businesses treat as basic infrastructure, the scale was extraordinary. This was not a regional blip or a single app going down. It was a global failure of the platform millions of companies depend on.
The three factors that combined
Microsoft's explanation, shared on November 16 by Charles Lamanna, executive vice president for Copilot, Agents and Platform, in a post on X, is that no single failure caused the outage. Three separate factors combined at the worst possible moment.
| Factor | What happened | Why it mattered |
|---|---|---|
| A latent software defect | A fix for Microsoft 365 networking gateway servers introduced lock contention in an internal process | Servers became overwhelmed and unresponsive under certain load |
| A Teams failover | About 15 hours before the outage, Teams moved from its alternative gateway to the primary gateway | The primary gateway, which also supports Exchange Online, took on extra load |
| Lost gateway capacity | Nearly 14% of gateway server capacity was already out of service | The system had far less headroom than usual when the defect struck |
| Any one of these on its own might have been manageable. Together, they were enough to bring down one of the world's biggest cloud platforms. | ||
| Lamanna also apologised for the disruption, acknowledging how much the outage had cost users and businesses. Microsoft tracked the incident under the IDs MO1550821 and EX1550543. |
The July bug at the heart of it
The most striking part of the explanation is how long the defect had been in place. The faulty code came from a fix prepared specifically for Microsoft 365 networking gateway servers, and it began rolling out in July 2026. It then ran in production around the world for more than three months without causing any visible impact. Nothing went wrong in July, August, September or October. The defect was latent — present in the code, but only triggered under particular conditions. The problem was lock contention inside an internal process. In simple terms:
- A "lock" is a mechanism that stops two parts of a system from changing the same data at the same time.
- When processes compete for the same lock too often, they end up waiting on each other instead of doing useful work.
- Under the right load conditions, that waiting cascades — servers slow down, stop responding, and eventually become overwhelmed.
That is what happened on November 12. Load on the networking gateways rose to the level that exposed the defect, and servers that had been running fine for months suddenly became unresponsive.
The networking gateway is a critical choke point. It sits between users and the Microsoft 365 services behind it, routing traffic to Exchange Online, Teams, OneDrive and the rest. When the gateway servers go down, users cannot reach the services at all — even though the services themselves may still be running.
Why testing missed the bug
One of the first questions after any outage like this is why testing did not catch the problem. Microsoft's answer is revealing: the load testing focused on weaker hardware, while the defect is worse on newer machines with more cores. That sounds counterintuitive. Faster hardware should handle more load, not less. But lock contention behaves differently:
- More processor cores mean more threads running at the same time.
- More threads competing for the same lock means more waiting, not more throughput.
- On weaker machines with fewer cores, the contention never reached the level that triggers the failure. So the tests passed, because they were run on hardware where the defect barely showed up. In production, on newer, more powerful gateway servers, the same code behaved very differently once load rose. This is a lesson that will be familiar to anyone who runs large systems. Testing on one class of hardware does not guarantee the same behaviour on another, and performance bugs can hide in exactly the gap between the test environment and the real one. Microsoft has not yet published the full Post-Incident Review, which was due later in the week of November 16. That document is expected to go into more detail on the testing gap and what will change.
Why Outlook stayed down longest
Not every Microsoft 365 service recovered at the same speed, and the reason comes down to failover — the ability to switch to a backup when the main system fails. Teams, OneDrive, SharePoint and the Office apps were able to fail over away from the faulty gateway. Once they moved, they recovered sooner, and many users saw those services come back while Outlook was still down. Exchange Online could not make the same switch. It had no failover path off the affected gateway, so Outlook stayed tied to servers that were unresponsive. That is why email was the last thing to return for many users, and why the outage felt, for most people, like an Outlook outage above all else. At the worst point, more than 80% of the networking gateway servers were unresponsive. With that much of the gateway fleet down, and Exchange Online unable to move elsewhere, there was no quick workaround. The only real fix was to remove the faulty code.
How Microsoft fixed it
Once engineers identified the defect, the fix itself was straightforward: revert the code path to the previously known good state. In other words, undo the July change and go back to the version that had worked before. Getting there took time. According to Microsoft's account:
- Around 30 hours to identify the problem and apply the fix
- Around 15 more hours to roll the fix out across the affected systems That timeline explains why the outage dragged on for more than a day. Finding a latent defect that had been harmless for three months is not a matter of spotting an obvious error. Engineers had to work out which of many possible causes was responsible, confirm it, and then deploy the revert safely across a global fleet. Microsoft was clear on one point throughout: there was no malicious activity involved, and this was not a cyberattack. For a global outage of this size, that question always comes up early, and the company ruled it out.
What the outage means for businesses
For the companies that rely on Microsoft 365, the November 12 outage was a reminder of how much depends on a single platform. When Outlook, Teams, OneDrive and SharePoint all go down together, there is often no easy fallback. A few practical lessons stand out:
- Email is still the backbone. For all the talk of chat and collaboration tools, most organisations discovered that losing email stops work fastest.
- Failover is not equal across services. Teams could move; Exchange Online could not. Businesses should know which of their critical services have a real failover path and which do not.
- Outages can come from old changes. The faulty code was deployed in July and caused no problems for months. A change does not have to be recent to be dangerous.
- Status pages matter. Microsoft's incident IDs, MO1550821 and EX1550543, were the reference points IT teams used to track the outage and communicate with staff. For IT administrators, the Post-Incident Review will be the document to watch. It should set out what Microsoft is changing — in testing, in gateway capacity, and in failover for Exchange Online — to stop the same combination from happening again.
What users should do now
For most users, there is nothing to fix. The services are back, and no action is needed on individual accounts. But a few checks are worth doing after any outage of this size:
- Check your sent mail. If you tried to send emails during the outage, confirm they actually went out. Some messages may have sat in the outbox or failed silently.
- Check calendar invites. Meetings created or changed during the outage may not have synced correctly to all attendees.
- Check shared files. Documents edited in OneDrive or SharePoint during the disruption may have sync conflicts that need resolving.
- Review your backup plan. If your business has no way to communicate when email is down, this is the week to set one up — even something as simple as an agreed messaging channel for outages. None of this is urgent for most people. But the outage showed how quickly a normal working day can unravel when the tools everyone uses stop working at once.
What to watch next
The story is not quite finished. Microsoft's full Post-Incident Review was due later in the week of November 16, and that document should answer the questions Lamanna's post left open:
- What exactly changes in load testing? Will Microsoft test on the same high-core-count hardware that runs in production?
- Will Exchange Online get a failover path? The inability to move off the faulty gateway is what kept Outlook down longest.
- What happens to gateway capacity? Nearly 14% of capacity was already out of service before the outage began, because of an unrelated issue from the previous day.
- Will the gateway architecture change? The fact that one gateway fleet could take down so many services at once is itself a design question. Regulators and large customers will also be watching. Outages of this scale tend to draw questions from governments and enterprise customers about resilience, and Microsoft will need to show that the fixes go beyond reverting one code change. For now, the explanation gives users something the outage itself did not: a clear account of what went wrong, and why. A bug from July, a failover 15 hours before, and a capacity shortfall from the day before — three separate threads that came together on November 12.
The bottom line
Microsoft's explanation of the November 12 outage is unusually specific, and unusually honest about how long the problem had been hiding. A software defect introduced in July ran silently for more than three months, then combined with a Teams failover and a 14% capacity shortfall to knock out more than 80% of the networking gateway servers. Outlook stayed down longest because Exchange Online, unlike Teams and OneDrive, could not fail over to a healthy gateway. The fix was a revert to known-good code, but it took about 30 hours to identify and apply, and 15 more hours to roll out. The full Post-Incident Review should fill in the remaining details. Until then, the message for users is simple: this was not an attack, it was a chain of failures — and the chain started with a fix that nobody knew was broken.
FAQs
What caused the Microsoft 365 outage on November 12, 2026?
Microsoft says three factors combined: a latent software defect from July 2026 that caused lock contention in its networking gateway servers, a Teams failover onto the same primary gateway about 15 hours earlier, and nearly 14% of gateway capacity already being out of service.
When did the Microsoft 365 outage happen and how long did it last?
The outage began on Thursday, November 12, 2026, with Microsoft first flagging it at 11:24 pm IST that day. It lasted more than 24 hours for many users, and the fix took about 30 hours to identify and apply, plus around 15 more hours to roll out.
Why was Outlook down longer than Teams and OneDrive?
Teams, OneDrive, SharePoint and Office apps could fail over away from the faulty networking gateway and recovered sooner. Exchange Online could not switch gateways, so Outlook stayed down until the faulty code was reverted.
Was the Microsoft 365 outage a cyberattack?
No. Microsoft has said there was no malicious activity involved and the outage was not a cyberattack. The cause was a software defect combined with a failover and a capacity shortfall.
What was the July bug behind the outage?
The defect came from a fix prepared for Microsoft 365 networking gateway servers, first deployed in July 2026. It caused lock contention in an internal process, making servers unresponsive under certain loads. Load testing missed it because tests focused on weaker hardware, while the defect is worse on newer machines with more cores.
How many people were affected by the outage?
The outage spread to more than 70 countries, with 120,000 to 130,000 reports at the peak on Downdetector. It affected Outlook, Exchange Online, Teams, OneDrive, SharePoint, Office apps, Copilot and other services, including government offices, courts and hospitals.
Was this article helpful?
Written By
TechorCoffeeContributing Writer
TechorCoffee is a technology reporter and software creator writing reviews and tutorials for TechOrCoffee.
Comments (0)
Leave a Comment
Read Next
Fri Oct 30 2026
Best AI Coding Tools 2026: Cursor, Copilot, Claude Code
Best AI coding tools 2026 compared: Cursor, GitHub Copilot, Claude Code, Codex, models, prices, and which tool fits your workflow.
Sat Nov 14 2026
Microsoft 365 Outage Hits 430 Million Users Worldwide
Microsoft 365 went down worldwide on 12 November 2026, hitting Outlook, Teams and Copilot for over a day. What happened, why, and what it means for you.
Sat Nov 14 2026
Nvidia CEO Jensen Huang Resigns After 33 Years at Top
NVIDIA has announced co-founder Jensen Huang has resigned as CEO after 33 years. CFO Colette Kress will serve as interim CEO during the search.