Gemini 4 Neon Is Here: Google's Fast New AI for Coding
Published (Updated )
Google has added a fourth model to its Gemini 4 family, and it is aimed squarely at the work developers actually do all day. Gemini 4 Neon launched on November 18, 2026, positioned between the heavyweight Carbon model and the speedy Hydrogen model — fast enough for everyday coding and agentic workflows, but strong enough for complex software engineering, knowledge work and science.
The quick answer:
- What launched: Gemini 4 Neon, Google DeepMind's newest model, on November 18, 2026
- Where it sits: between Gemini 4 Carbon (maximum capability) and Gemini 4 Hydrogen (fastest, cheapest)
- Context window: 1 million tokens, shared across input, thinking and output
- Price: $3 per million input tokens and $15 per million output tokens, with cached input at $0.15
- Where to get it: Gemini API, Google AI Studio, Vertex AI Model Garden, Google Antigravity, and the Gemini app for Pro and Ultra subscribers
- Best for: software engineering, coding agents, knowledge work and scientific workflows
A fourth Gemini 4 model in about a month
Google has moved fast with the Gemini 4 lineup. Argon arrived in late September, Carbon followed in late October, Hydrogen landed on November 12, and now Neon completes the set — four models in roughly four weeks. That pace tells its own story. Google is no longer shipping one flagship model and asking everyone to use it for everything. Instead, it is building a ladder of models, each tuned for a different balance of capability, speed and cost. Neon is the middle rung: the model you reach for when Hydrogen is not quite strong enough and Carbon is more than the job needs. Neon is adapted from Gemini 4 Carbon, according to the model card Google DeepMind published on launch day. That lineage matters, because it means Neon inherits much of Carbon's reasoning ability while being packaged for faster, higher-frequency work. Google describes it as a fast reasoning model for the middle of its lineup — strong enough for complex software engineering, knowledge work and science, but built for speed and cost rather than maximum capability. The launch itself had a small twist. Hours before the official announcement, pricing for an unannounced Gemini 4 Neon surfaced in Google Cloud's billing catalog — $3 per million input tokens and $15 per million output tokens. By the evening, the documentation page that had returned a 404 in the morning described the model in full, a model card was live on DeepMind's site, and the model appeared in the Vertex AI Model Garden and Google AI Studio. The leak turned out to be exactly right.
What Neon can actually do
The official model card lays out Neon's technical footprint in detail, and it is a substantial one.
- Multimodal inputs: Neon accepts text, image, audio, video and PDF inputs, so it can work across spreadsheets, PDFs, charts, audio and video within a single request
- 1 million-token context: a unified context window of 1,048,576 tokens, shared across input, thinking and output
- Long outputs: default synchronous output of up to 65,536 combined thinking and output tokens, with a long-decode mode that can continue up to the remaining shared budget
- Text output only: Neon returns text — it does not generate images or audio, and it does not support the Live API
- Knowledge cutoff: March 2026, so anything newer than that is outside what the model was trained on
- Structured outputs: it can produce structured outputs from the material you feed it
That combination — a million-token window, multimodal input and long outputs — is what makes Neon a workhorse for agents and long tasks rather than a media model. A coding agent can load a whole repository, a set of design documents and a bug report into one request and keep working through them without losing the thread. The model card also includes evaluations spanning coding agents, knowledge work, science and long-context tasks, along with frontier safety limits. Google is clear that hallucinations remain possible — the card says so explicitly — which is worth remembering before you trust Neon with anything you have not checked.
How much it costs, and why the price is odd
Neon's pricing is $3 per million input tokens, $15 per million output tokens, and $0.15 per million cached input tokens — a 95% discount on cached input, according to Google. That is exactly double Hydrogen, which launched on November 12 at $1.50 per million input tokens and $7.50 per million output tokens. That looks like a strange place to sit until you look at the calendar. Google's introductory rates for Carbon and Argon end on December 1, and Neon costs 50% more per token than Carbon through November 30. After that, the picture flips. Google is selling Neon not on raw token price but on cost per task — the company claims Neon delivers about 32% lower cost per task than Carbon, and one launch post put the saving at around 17% per task. The key numbers for buyers:
- Input: $3.00 per million tokens
- Output (including thinking): $15.00 per million tokens
- Cached input: $0.15 per million tokens
- Hydrogen comparison: exactly double Hydrogen's $1.50 / $7.50 rates
- Cost per task: Google claims roughly 32% lower than Carbon
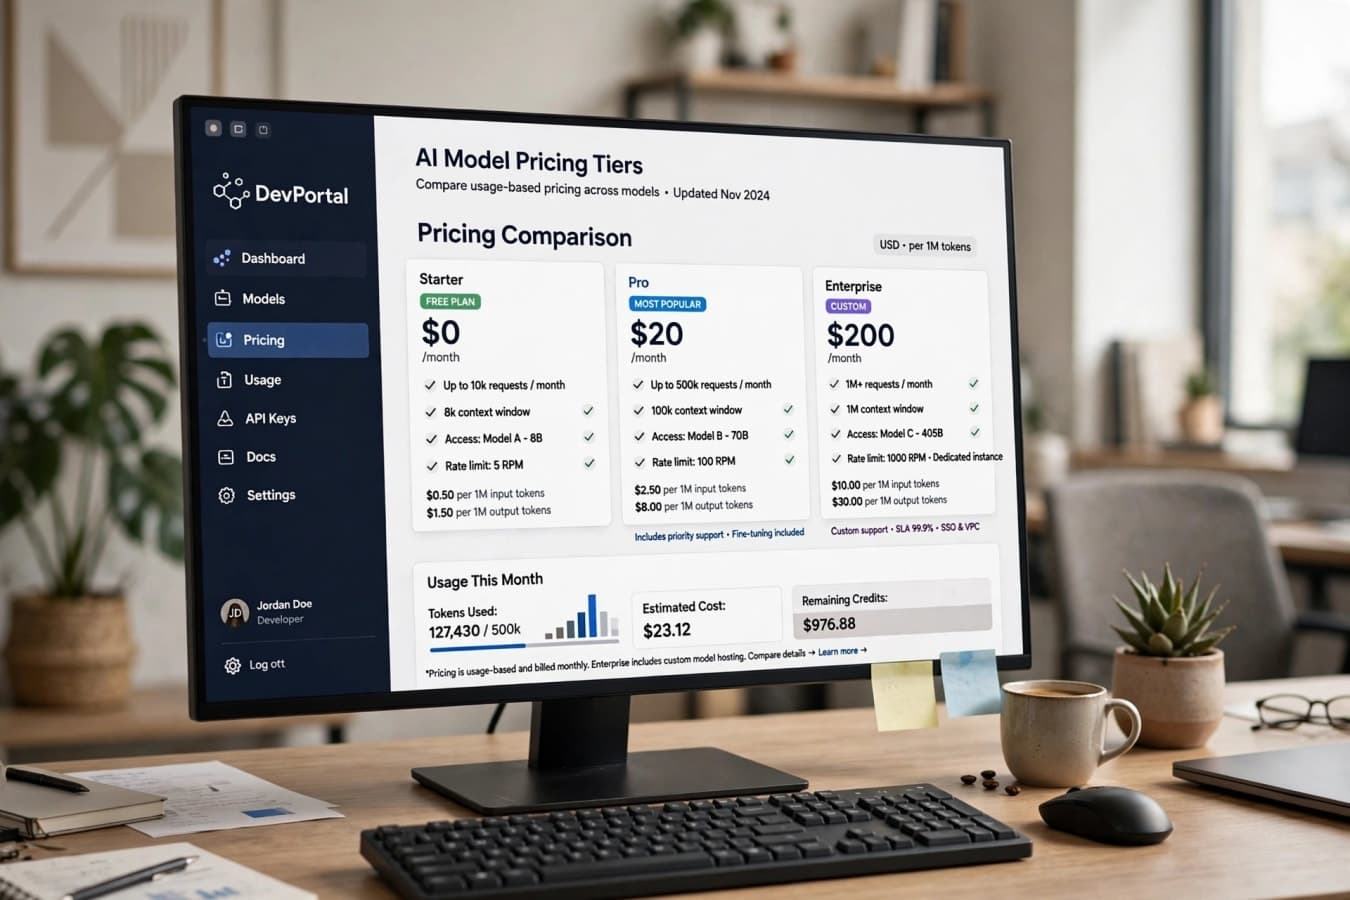
Whether that cost-per-task claim holds up in real workloads is still an open question. Google has published no independent benchmarks for Neon yet — the model card and documentation describe capabilities, not scores — so the "close to Carbon" framing rests on Google's own numbers for now.
Where Neon ranks
Google says Neon ranks third on the Artificial Analysis Intelligence Index, scoring 61 at its highest thinking level. Other early rankings paint a mixed but encouraging picture: one benchmark index placed Neon second overall at 70.9%, just 0.4 points behind Claude Fable 5.2, at less than half the cost per task. In DeepMind's own SWE-sweep evaluation, Neon scored 39.0% inside Google Antigravity and 12.8% in a shared mini-SWE setup. The model card also compares Neon with Claude Opus 5.5 and GPT-6.2 Sol across coding evaluations. The honest summary is that Neon looks competitive on the numbers available, but those numbers mostly come from Google or from early third-party indexes. Independent, head-to-head testing against Claude and GPT-6.2 in real developer workflows has not had time to happen yet. If you are choosing a model for production coding work, treat the early rankings as a reason to try Neon, not as a final verdict.
Where you can use Neon right now
Neon is rolling out across Google's AI surfaces from launch day:
- Gemini API: available in the paid tier through Google AI Studio and Android Studio
- Gemini for business: through the API and the model dropdown
- Google Antigravity: for paid Google AI Pro and Ultra subscribers
- Gemini app: for Pro and Ultra subscribers, in the model picker
- Vertex AI: listed in the Model Garden for enterprise use
There is also a cyber-tuned variant of Neon. That version is not going to general availability — it is reaching eligible members of Google's Fairwind Program over the coming days, aimed at cyber defence work rather than everyday coding. For most developers, the practical route is the Gemini API or Antigravity. If you already use Antigravity for coding, Neon should appear in the model list for Pro and Ultra plans. If you build with the API, the stable model ID is gemini-4-neon, and implicit prompt caching is available at launch with a 4,096-token minimum.
Neon vs the rest of the Gemini 4 family
With four models in the family, the obvious question is which one to use. Here is how they line up:
- Gemini 4 Argon: the earliest of the four, from late September — the entry point of the family
- Gemini 4 Carbon: the most demanding frontier reasoning tier, built for the hardest long-horizon projects
- Gemini 4 Hydrogen: the fast everyday model, released November 12 at $1.50 / $7.50 per million tokens
- Gemini 4 Neon: the new middle tier — Carbon-level reasoning adapted for speed, priced at $3 / $15
The rule of thumb Google is pushing is simple. Use Hydrogen for fast, everyday execution where cost matters most. Use Neon for frequent, complex work — coding agents, multi-step workflows, big codebases — where you need real reasoning but cannot afford Carbon's price or latency. Use Carbon for the hardest problems where nothing else will do. That ladder only works if the gaps between the rungs are real. Hydrogen is genuinely cheap and fast. Carbon is genuinely the strongest. Neon has to prove that its middle position is more than a pricing exercise — that it is noticeably better than Hydrogen on hard tasks and noticeably cheaper or faster than Carbon on everyday ones. The early benchmark hints suggest it is, but the proof will come from developers running it on their own code.
What this means for developers
Neon's launch matters less as a single model and more as a sign of where Google is heading. The company is now shipping models at a pace of roughly one a month, each one aimed at a specific slice of work rather than trying to be everything to everyone. For developers, that means three practical things:
- Coding agents get a better default: Neon is built for agentic workflows — the kind of multi-step, tool-using coding work that Antigravity and Codex-style tools do all day. A million-token context means an agent can hold a whole project in view.
- Cost per task is the new battleground: Google is not competing on token price alone. It is arguing that a slightly more expensive model that finishes a task in fewer steps is cheaper overall. If that argument holds, expect every vendor to start quoting cost per task instead of cost per token.
- The choice is getting harder, not easier: four Gemini models, plus Claude, GPT-6.2 and open-weight options, means picking a model is now a real decision. The right answer depends on your workload, your budget and how much you value speed over capability.
If you are already in Google's ecosystem — using Antigravity, the Gemini API or Vertex AI — Neon is worth trying on your hardest coding tasks this week. Compare it directly against Hydrogen on the same job and see whether the extra reasoning is worth double the token price. That test, run on your own code, will tell you more than any launch-day benchmark.
The bottom line
Gemini 4 Neon is Google's bet that the middle of the model ladder is where most real work happens. It is not the smartest model Google makes, and it is not the cheapest — but it may be the one that fits the way developers actually build software: big codebases, long tasks, agents that need to keep context, and a budget that has to stretch. The model is live now across the Gemini API, AI Studio, Antigravity and the Gemini app. The pricing is clear, the context window is large, and the early rankings are promising. What is missing is independent proof that it beats Hydrogen where it counts and undercuts Carbon where it matters. That proof will arrive over the next few weeks, one developer at a time.
FAQs
What is Gemini 4 Neon?
Gemini 4 Neon is Google DeepMind's newest AI model, launched November 18, 2026. It is a fast reasoning model for software engineering, knowledge work and science, positioned between Gemini 4 Carbon and Gemini 4 Hydrogen in capability and price.
How much does Gemini 4 Neon cost?
Neon costs $3 per million input tokens and $15 per million output tokens, with cached input at $0.15 per million tokens. That is exactly double Gemini 4 Hydrogen's $1.50 / $7.50 rates, but Google claims about 32% lower cost per task than Carbon.
What is Gemini 4 Neon's context window?
Neon has a unified context window of 1,048,576 tokens — about 1 million tokens — shared across input, thinking and output. It accepts text, image, audio, video and PDF inputs.
Where can I use Gemini 4 Neon?
Neon is available through the Gemini API in Google AI Studio and Android Studio, in Gemini for business, in Google Antigravity for Pro and Ultra subscribers, in the Gemini app for Pro and Ultra subscribers, and in the Vertex AI Model Garden.
Is Gemini 4 Neon better than Gemini 4 Carbon?
No — Carbon remains Google's most capable model for the hardest long-horizon projects. Neon is adapted from Carbon but tuned for speed and cost, aimed at frequent, complex work rather than maximum capability.
Does Gemini 4 Neon generate images or audio?
No. Neon returns text only. It does not generate images or audio, and it does not support the Live API.
Was this article helpful?
Written By
TechorCoffeeContributing Writer
TechorCoffee is a technology reporter and software creator writing reviews and tutorials for TechOrCoffee.
Comments (0)
Leave a Comment
Read Next

Tue Apr 21 2026
Best AI Tools for Students & Creators in 2026:Complete Guide
AI tools are transforming how students learn and creators produce content. From writing assistants to design and research tools, these platforms save time, enhance creativity, and improve efficiency. Choosing the right AI stack can significantly boost productivity and output quality.
Tue Jun 16 2026
Apple Intelligence 2.0: Siri AI & iOS 27 at WWDC 2026
Apple Intelligence 2.0 is here. I cover Siri AI, iOS 27 release dates, supported devices, and how Apple's new AI really compares to ChatGPT and Gemini.
Tue Oct 13 2026
Gemini 4 Argon: Everything You Need to Know
Gemini 4 Argon is Google’s new flagship AI model. See its benchmarks vs GPT-6 Astra and Claude, pricing, 1M-token output, safety features and how to get access.